
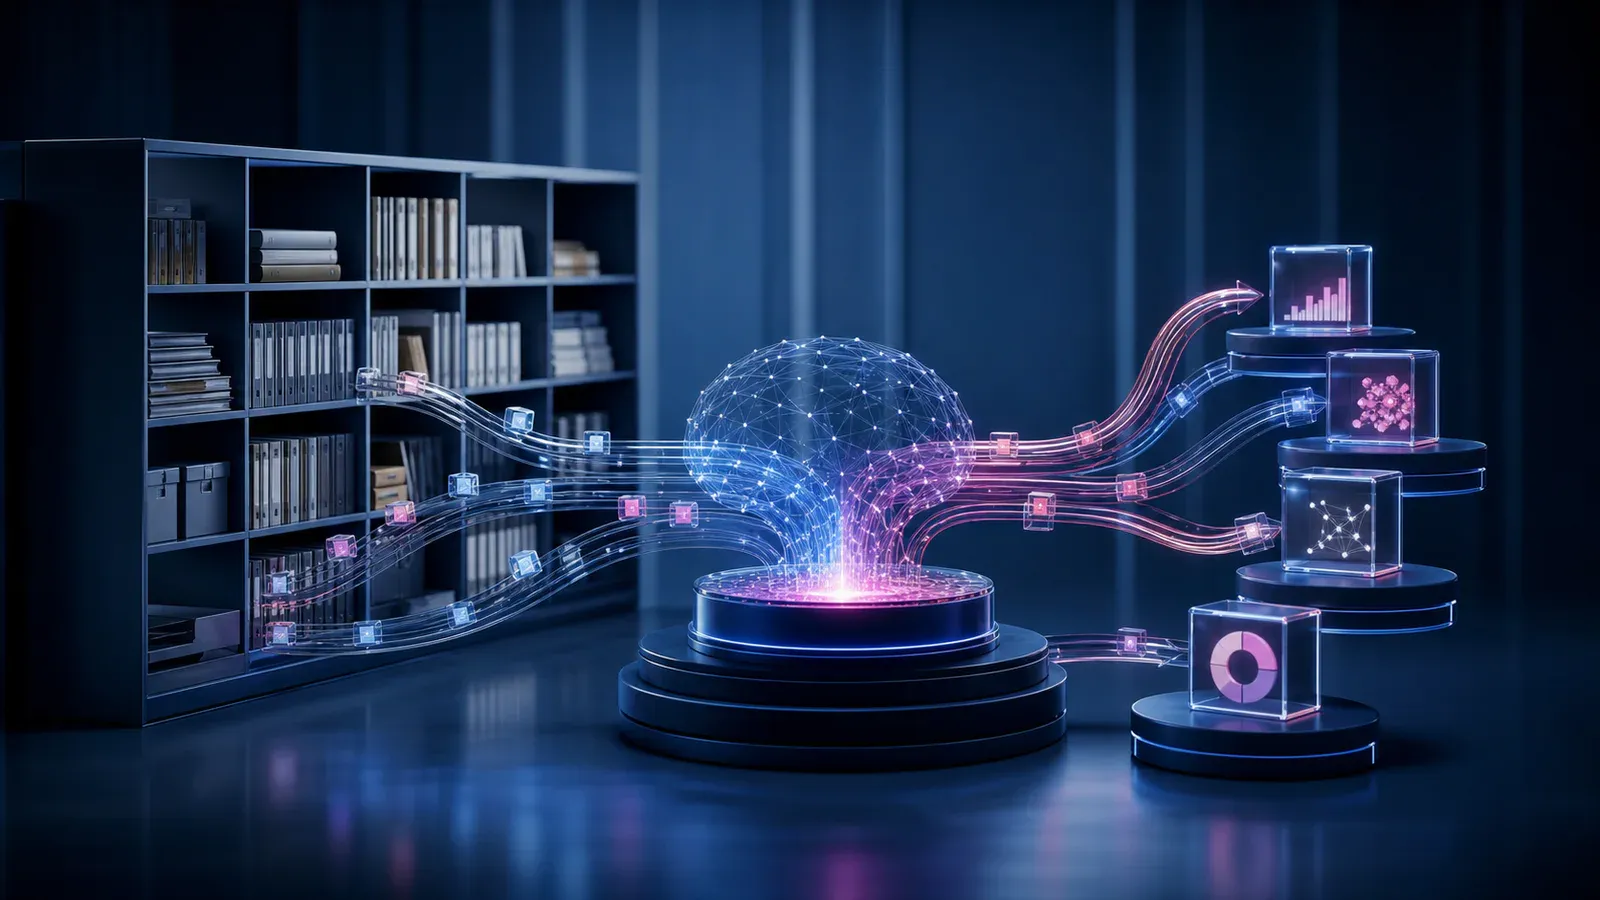
Large language models can write fluent answers, but they do not automatically know an organisation’s current policies, customer records or operating knowledge. Retrieval-augmented generation—RAG—connects a model to approved information at the moment a question is asked.
RAG retrieves relevant passages from a controlled knowledge source and includes them as evidence for a language model’s response. It improves freshness and traceability, but only when retrieval quality and access control are engineered well.
RAG is not a truth switch. If the system retrieves the wrong passage, an outdated document or information the user should not see, the answer can still be confidently wrong. The production challenge is the complete retrieval system.
How RAG works
A basic RAG workflow has five steps:
- Documents are collected, cleaned and split into useful sections.
- Each section is converted into a numerical representation called an embedding.
- A user question is embedded and matched to relevant sections.
- Selected passages are placed in the model’s context with clear instructions.
- The model produces an answer, ideally with citations to the evidence.
More advanced systems combine semantic and keyword search, rerank results, apply metadata filters and use multiple retrieval passes. Complexity should respond to measured failure, not precede it.
Choose RAG for the right job
RAG is a strong fit when answers depend on changing or private knowledge: policies, product documentation, contracts, service history or technical runbooks. It is also useful when a reader needs to see where an answer came from.
It is not always necessary. A deterministic database query is better for an exact account balance. A search interface may be better when users need to inspect complete documents. Fine-tuning is better suited to changing stable behaviour or style than injecting frequently updated facts.
Start with the job. If the output must combine language understanding with governed knowledge, RAG may fit.
Engineer the knowledge layer
Document quality sets the ceiling for answer quality. Remove duplicates, mark authoritative versions and attach metadata such as owner, date, product, region and confidentiality. Decide how changes and deletions propagate into the index.
Chunking should respect meaning. Splitting by a fixed character count can separate a rule from its exception. Use document structure where possible, retain titles and test multiple chunk sizes against real questions.
Access control must travel with every chunk. Filter retrieval using the requesting user’s permissions before evidence reaches the model. Post-generation redaction is too late if restricted data was already placed in context.
Make evidence visible
Return citations that identify the source and relevant section. Allow users to open the evidence. If sources conflict or confidence is low, the system should say so and offer the documents rather than invent a resolution.
Traceability helps users verify answers and helps engineers diagnose them. Log the question, retrieved passages, ranking scores, model version, prompt version and response subject to privacy and retention requirements.
The NIST AI Risk Management Framework emphasises context and measurement. In RAG, that means knowing which knowledge was permitted, retrieved and used.
Evaluate retrieval and generation separately
End-to-end accuracy alone does not explain failure. Measure retrieval first:
- Did the correct source appear in the candidate set?
- Was it ranked high enough to enter context?
- Did metadata filters include the right scope?
- Were outdated or restricted documents excluded?
Then evaluate generation:
- Is every material claim supported by retrieved evidence?
- Does the answer preserve qualifications and exceptions?
- Does it decline when evidence is missing?
- Are citations accurate and useful?
Build an evaluation set from real questions, including ambiguous wording, outdated terminology and adversarial requests. Review results by knowledge domain rather than hiding them in one average.
Operate for change
Monitor unanswered questions, retrieval misses, user corrections, stale sources, latency and cost. Give knowledge owners a way to improve documents when repeated questions reveal gaps. Version indexes and prompts so changes can be rolled back.
RAG quality often improves more through better documents and retrieval than through switching models. That is encouraging: the organisation can control much of the system’s usefulness.
Vinove’s Agentra focuses on AI for real business work, while ValueCoders provides the engineering depth to integrate systems around it. Both sit under the same technology-that-works standard.
The RAG readiness checklist
Before launch, confirm that authoritative sources are identified, permissions are enforced during retrieval, citations open the right evidence, retrieval and generation have separate evaluations, missing evidence produces a safe response and one team owns knowledge freshness.
RAG makes enterprise AI more grounded, not automatically correct. Its value comes from connecting generation to trusted evidence through an architecture that remains secure, measurable and understandable.

Add to the conversation.
Be the first reader to add a useful perspective.